Как честно сравнить системы памяти для AI-агентов
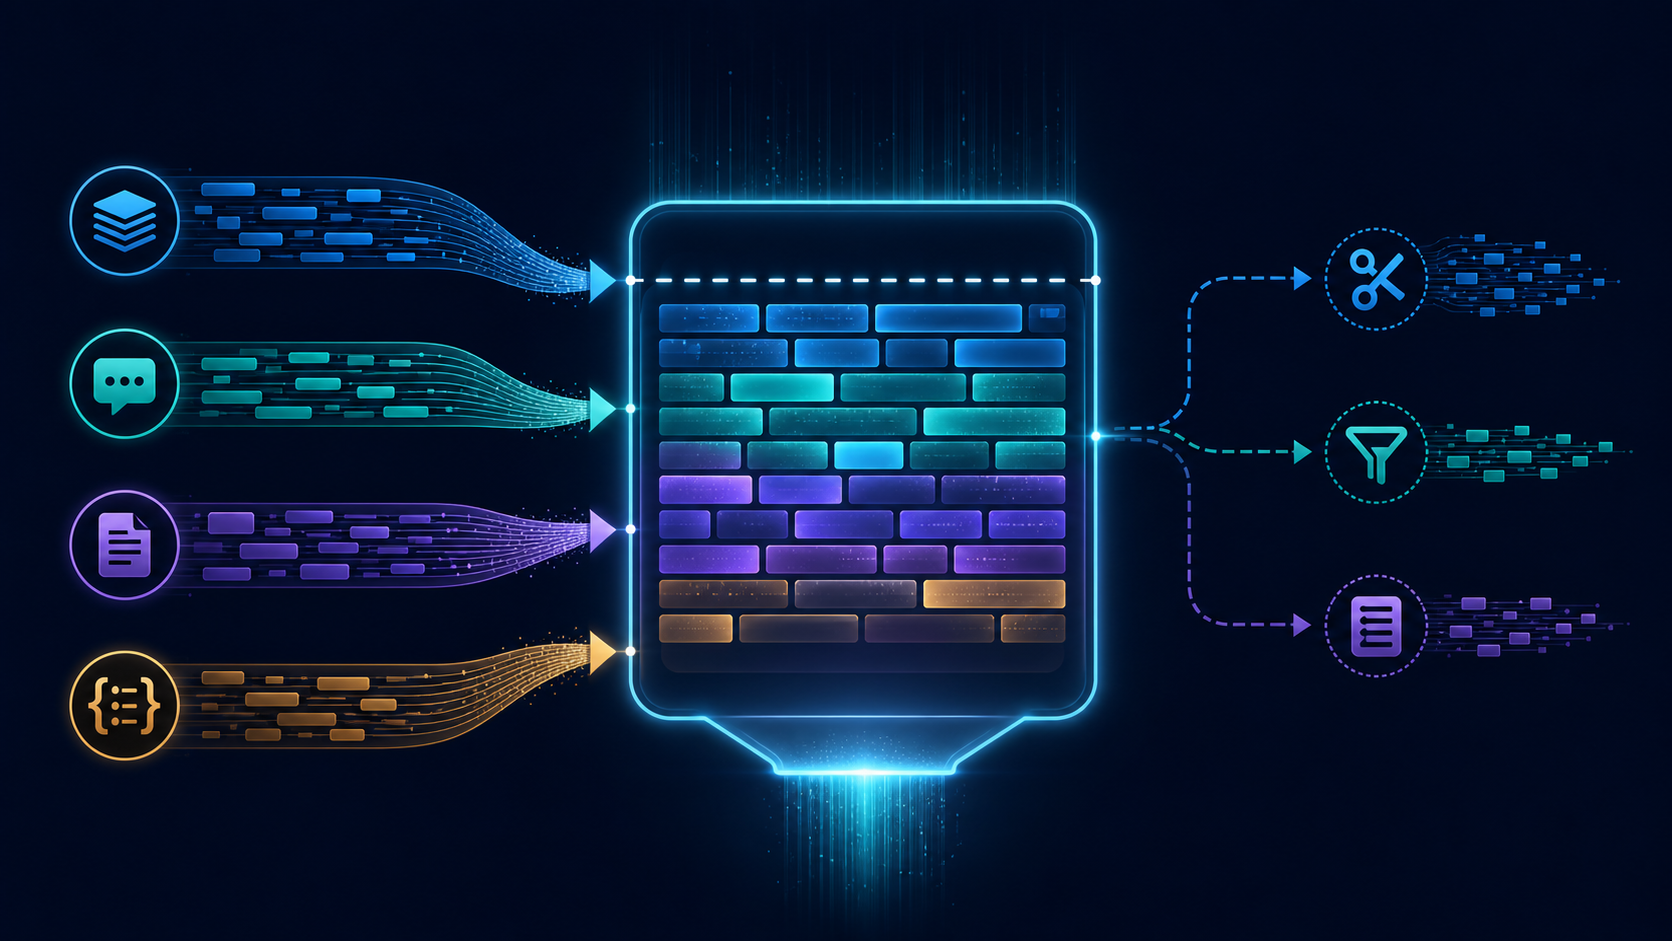
You read that memory system A beats memory system B by double digits, then look more closely: A's numbers came from a stronger answer model, a longer prompt, a bigger context and a lenient grader. That isn't a comparison of memory. It's a comparison of two whole pipelines that happen to contain memory. This guide builds a small, reproducible benchmark that holds everything constant except the memory layer. Every system sits behind the same two calls, Add and Search. The same pinned model writes every answer from the same prompt, inside the same token budget, and one blinded procedure scores them all.
What you get at the end: a working harness (about 400 lines of Python), a dataset format with gold evidence, two control baselines that show whether your test itself is broken, and a report template that gives differences with confidence intervals instead of a single leaderboard number.
What this article does not contain: results. We don't publish scores for any product here, and the numbers in the examples are placeholders. The point is the procedure. Run it on your own data and fill the table yourself.
1. Why most memory comparisons are not comparisons
Agent memory is the component that stores information from past interactions and brings back the relevant parts later. In a typical agent, a question passes through at least five stages, and any of them can move the final score:
- Ingestion. How conversation turns are stored: raw text, extracted facts, summaries, a graph.
- Retrieval. Which stored items come back for a query, and in what order.
- Context assembly. How many retrieved items reach the model and how they are formatted.
- Answer generation. Which LLM answers, with which prompt and which sampling settings.
- Evaluation. Who decides whether an answer is correct, and by what rule.
Only stages 1 and 2 are "the memory system". Stages 3–5 belong to the harness. Published comparisons often change them between systems, sometimes without noticing:
- Different answer models. Vendor A reports results with its recommended model and vendor B with another one. The gap may come from the models alone.
- Different prompts. One prompt says "if unsure, say you don't know". The other pushes the model to always answer. Questions about information that was never mentioned (abstention questions) flip completely.
- Different context budgets. A system that returns 30 long chunks gets more chances than one that returns 5 short facts. That measures budget, not memory quality.
- Different graders. Exact string match punishes verbose answers. A lenient LLM-as-judge rewards them. A grader that can see which system produced the answer can be biased in either direction.
- Hidden extra models. Some memory systems call an LLM during ingestion to extract facts. If that internal model is much stronger than the answer model, part of the reasoning is done before the question is ever asked.
- Race conditions. Asynchronous indexing means that a search issued right after
Addcan miss data that would be found a few seconds later. The system looks worse because of timing, not quality.
The fix is not complicated, but it has to be done on purpose. You write a fairness contract and build a harness that enforces it.
2. The fairness contract
Write this down before writing any code, and keep it with the results. It lists what is held constant and what is allowed to vary.
| Held constant across all systems | Allowed to vary (and must be recorded) |
|---|---|
| Dataset file and its SHA-256 hash | Storage format (raw turns, facts, summaries, graph) |
Order and grouping of Add calls (one call per session, in chronological order) | Indexing method (embeddings, keyword index, hybrid) |
| Search query string (the question text, unchanged) | Internal ranking and re-ranking |
Top-k requested from Search | Internal extraction model, if any (its ID goes in the manifest) |
| Context token budget and formatting template | Latency and cost, which are measured and reported, not normalized |
| Answer model ID, prompt, temperature, max tokens | |
| Judge model ID, judge prompt, blinding and shuffling | |
| Scoring script and statistical procedure |
Two rules follow from the contract.
Rule 1: only Search is used at question time. Many memory products also offer a "chat" or "answer" endpoint that retrieves and generates in one step. Don't use it in the comparison, because it brings in the vendor's own prompt and model. If you want to test that endpoint, run it as a separate, clearly labeled experiment.
Rule 2: if a system uses an internal LLM, report the system together with that model. When you can configure the internal model, set it to the same model ID as the answer model. When you can't, note it in the results table. A row such as "System X (internal extractor: model Y)" is honest. "System X" alone is not.
3. The concrete case: a long-running engineering assistant
As a running example we use a synthetic assistant that works with one engineering team over several months. The dataset below is illustrative and written for this article. It is not taken from real users. It contains no personal data, which is how your own test set should look too.
Each case is a sequence of timestamped sessions followed by questions. Each question has a gold answer and a list of evidence turn IDs: the turns that contain the information needed to answer it. The evidence IDs let us measure retrieval separately from answering.
{"case_id": "c001",
 "sessions": [
  {"session_id": "s1", "timestamp": "2026-03-02T10:00:00Z", "turns": [
    {"turn_id": "c001-s1t1", "role": "user", "text": "The billing service runs on Postgres 14, we pinned it last year."},
    {"turn_id": "c001-s1t2", "role": "assistant", "text": "Noted: billing uses Postgres 14."},
    {"turn_id": "c001-s1t3", "role": "user", "text": "Search service is on Elasticsearch, unrelated to billing."}]},
  {"session_id": "s2", "timestamp": "2026-05-11T09:30:00Z", "turns": [
    {"turn_id": "c001-s2t1", "role": "user", "text": "We finished migrating billing to Postgres 16 this weekend."},
    {"turn_id": "c001-s2t2", "role": "assistant", "text": "Updated: billing now on Postgres 16."}]},
  {"session_id": "s3", "timestamp": "2026-05-25T14:00:00Z", "turns": [
    {"turn_id": "c001-s3t1", "role": "user", "text": "Release freeze for billing starts June 8 and lasts two weeks."}]}
 ],
 "questions": [
  {"qid": "c001q1", "type": "knowledge_update", "asked_at": "2026-06-01",
   "question": "Which Postgres version does the billing service run on?",
   "gold_answer": "Postgres 16", "evidence": ["c001-s2t1"]},
  {"qid": "c001q2", "type": "temporal", "asked_at": "2026-06-01",
   "question": "When does the billing release freeze end?",
   "gold_answer": "June 22", "evidence": ["c001-s3t1"]},
  {"qid": "c001q3", "type": "abstention", "asked_at": "2026-06-01",
   "question": "Which Redis version does billing use?",
   "gold_answer": "I don't know", "evidence": []}
 ]}
The file is JSON Lines with one case per line. The case is pretty-printed above only for readability.
The three questions stress three different weaknesses:
- c001q1, knowledge update. Both "Postgres 14" and "Postgres 16" are relevant to the query. A system that ranks by similarity alone may put the outdated fact first.
- c001q2, temporal reasoning. The answer has to be computed from a start date and a duration. Retrieval has to find the turn, and the answer model has to do the arithmetic.
- c001q3, abstention. Redis was never mentioned. A system that returns "something about billing" anyway invites a hallucination. The correct behavior is to decline.
For a test you can trust, aim for at least 30–50 cases and 150+ questions, spread over these types:
| Type | What it tests | Construction tip |
|---|---|---|
single_hop | Basic recall of one stated fact | Bury it among 10+ unrelated turns |
knowledge_update | Preferring the newer of conflicting facts | Keep the wording of the old and new facts very similar |
temporal | Dates, durations, "before/after" | Require a calculation, not a lookup |
multi_session | Combining facts from 2+ sessions | List all evidence turns. Recall is measured as "all found" |
abstention | Not inventing missing facts | Ask about an entity close to real ones (Redis next to Postgres) |
Add distractors on purpose: turns that share vocabulary with a question but don't answer it, such as "Search service is on Elasticsearch" above. Without distractors, even a trivial keyword matcher looks excellent.
4. One interface: Add and Search
Every system under test is wrapped in one adapter with four methods. reset and flush exist so the benchmark doesn't silently test leftover state or indexing lag.
Project layout:
memory-bench/
  config.yaml
  data/cases.jsonl
  interface.py
  context.py
  llm.py
  run.py
  judge.py
  score.py
  manifest.py
  backends/
    __init__.py
    keyword.py
    http_adapter.py
  runs/        # one JSONL per system
results/ # verdicts and reports, kept separate from runs/interface.py:
from dataclasses import dataclass, field
from typing import Protocol


@dataclass(frozen=True)
class MemoryItem:
    item_id: str                                  # stable id, e.g. "c001-s2t1"
    text: str
    metadata: dict = field(default_factory=dict)  # session_id, timestamp, role


@dataclass(frozen=True)
class Hit:
    text: str
    score: float
    source_ids: tuple = ()   # provenance: which MemoryItem ids produced this hit
    timestamp: str = ""


class MemoryBackend(Protocol):
    name: str
    version: str

    def reset(self, namespace: str) -> None: ...
    def add(self, namespace: str, items: list[MemoryItem]) -> None: ...
    def flush(self, namespace: str, timeout_s: float) -> None: ...
    def search(self, namespace: str, query: str, k: int) -> list[Hit]: ...
The important field is source_ids. It carries provenance. If a system rewrites turns into extracted facts, each fact should still point back to the turns it came from. When a system can't report provenance, its retrieval recall@k can't be measured. For that system you can only report end-to-end accuracy, and you must say so in the results instead of guessing.
4.1 A transparent reference backend
Start with a deliberately simple backend that has no dependencies. It is not meant to be good. It gives you a floor that anyone can reproduce byte-for-byte, and it lets you debug the harness before you spend money on API calls.
backends/keyword.py:
import re
from collections import Counter, defaultdict

from interface import Hit, MemoryItem

TOKEN = re.compile(r"\w+", re.UNICODE)


def tokens(text: str) -> list[str]:
    return [t.lower() for t in TOKEN.findall(text)]


class KeywordBackend:
    name = "keyword-overlap"
    version = "0.1"

    def __init__(self):
        self._store = defaultdict(list)

    def reset(self, namespace):
        self._store[namespace] = []

    def add(self, namespace, items):
        self._store[namespace].extend(items)

    def flush(self, namespace, timeout_s):
        return None  # synchronous: searchable immediately

    def search(self, namespace, query, k):
        q = Counter(tokens(query))
        scored = []
        for it in self._store[namespace]:
            doc = Counter(tokens(it.text))
            overlap = sum(min(c, q[t]) for t, c in doc.items())
            if overlap:
                scored.append((overlap, it.metadata.get("timestamp", ""), it))
        # Ties are broken by newer timestamp; Python's sort is stable for the rest.
        scored.sort(key=lambda x: (x[0], x[1]), reverse=True)
        return [
            Hit(text=it.text, score=float(s), source_ids=(it.item_id,),
                timestamp=ts)
            for s, ts, it in scored[:k]
        ]
4.2 An adapter template for a real memory service
Real systems, whether hosted or self-hosted, get a thin adapter. The endpoint paths below are placeholders. Replace them with the API of the system you are testing. Don't treat them as any product's actual API.
backends/http_adapter.py:
import os
import time

import requests

from interface import Hit


class HttpMemoryAdapter:
    """Template. Endpoint paths and payload fields are placeholders."""

    def __init__(self, base_url, name="http-memory", version="unknown",
                 api_key_env="MEMORY_API_KEY", timeout_s=30):
        self.base_url = base_url.rstrip("/")
        self.name = name
        self.version = version
        self.timeout_s = timeout_s
        self.headers = {"Authorization": f"Bearer {os.environ[api_key_env]}"}

    def reset(self, namespace):
        r = requests.delete(f"{self.base_url}/namespaces/{namespace}",
                            headers=self.headers, timeout=self.timeout_s)
        if r.status_code not in (200, 204, 404):
            r.raise_for_status()

    def add(self, namespace, items):
        payload = {"items": [{"id": i.item_id, "text": i.text,
                              "metadata": i.metadata} for i in items]}
        r = requests.post(f"{self.base_url}/namespaces/{namespace}/items",
                          json=payload, headers=self.headers,
                          timeout=self.timeout_s)
        r.raise_for_status()

    def flush(self, namespace, timeout_s):
        deadline = time.monotonic() + timeout_s
        while time.monotonic() < deadline:
            r = requests.get(f"{self.base_url}/namespaces/{namespace}/status",
                             headers=self.headers, timeout=self.timeout_s)
            r.raise_for_status()
            if r.json().get("state") == "ready":
                return
            time.sleep(1.0)
        raise TimeoutError(f"{self.name}: namespace {namespace} not ready")

    def search(self, namespace, query, k):
        r = requests.post(f"{self.base_url}/namespaces/{namespace}/search",
                          json={"query": query, "k": k},
                          headers=self.headers, timeout=self.timeout_s)
        r.raise_for_status()
        hits = []
        for h in r.json().get("results", []):
            meta = h.get("metadata", {})
            hits.append(Hit(text=h["text"], score=float(h.get("score", 0.0)),
                            source_ids=tuple(meta.get("source_ids", [])),
                            timestamp=meta.get("timestamp", "")))
        return hits
If the system has no readiness endpoint, write flush as a probe instead: after ingestion, search for a sentinel phrase you added and wait until it shows up. If the system offers neither, wait a fixed delay and record the delay in the manifest. In that case "ready" is an assumption, not a verified state.
backends/__init__.py:
def load_backend(name, cfg):
    if name == "keyword":
        from backends.keyword import KeywordBackend
        return KeywordBackend()
    if name == "http":
        from backends.http_adapter import HttpMemoryAdapter
        return HttpMemoryAdapter(**cfg["http_backend"])
    raise ValueError(f"unknown backend: {name}")
5. The shared pipeline: context, answer, record
5.1 Pin everything in one config file
config.yaml:
run_id: mem-2026-10-17-a
dataset: data/cases.jsonl
seed: 7

top_k: 10
context_token_budget: 1200
flush_timeout_s: 120

answer_model: "REPLACE_WITH_PINNED_MODEL_ID"
answer_max_tokens: 200
judge_model: "REPLACE_WITH_PINNED_JUDGE_MODEL_ID"

answer_prompt: |
  You answer questions about a long-running conversation, using only the memories below.
  Current date: {asked_at}

  Memories (most relevant first, with the time they were recorded):
  {context}

  Question: {question}

  Rules:
  - If memories conflict, prefer the most recent one.
  - If the memories do not contain the answer, reply exactly: I don't know
  - Answer in one short sentence.

http_backend:
  base_url: "https://memory.example.internal"
  name: "system-under-test"
  version: "record-the-exact-version-here"
Use a dated, pinned model ID, not a moving alias like "latest". If your provider only offers aliases, record the resolved model name that comes back in the API response for every call.
Never put API keys in this file. Read them from environment variables, keep the variables out of the repository, and make sure they don't end up in logs or run files.
5.2 A fixed context budget
Every system gets the same number of tokens in the answer prompt. Whatever doesn't fit is cut off by rank, the same way for everyone. context.py:
def approx_tokens(s: str) -> int:
    # Crude but identical for every backend. Swap in the answer model's
    # tokenizer if you have it; the point is that all systems are counted alike.
    return max(1, len(s) // 4)


def build_context(hits, budget):
    lines, kept, used = [], [], 0
    for rank, h in enumerate(hits, 1):
        line = f"[{rank}] ({h.timestamp or 'unknown time'}) {h.text}"
        cost = approx_tokens(line)
        if used + cost > budget:
            break
        lines.append(line)
        kept.append(h)
        used += cost
    return "\n".join(lines), kept, used
Note the bias of len(s) // 4. It undercounts tokens for Cyrillic and many other scripts, so with non-English data the real prompt is longer than the budget suggests. This doesn't make the comparison unfair, because every system is counted the same way. It does matter if you compare results across languages, and in that case you should switch to the real tokenizer.
5.3 One answer model client
llm.py assumes an OpenAI-compatible chat endpoint. Many providers and local servers offer one. Adapt it if yours doesn't:
import os

from openai import OpenAI

_client = OpenAI(base_url=os.environ.get("LLM_BASE_URL"),
                 api_key=os.environ["LLM_API_KEY"])


def complete(model, prompt, temperature=0.0, seed=None, max_tokens=256):
    kwargs = dict(model=model, temperature=temperature, max_tokens=max_tokens,
                  messages=[{"role": "user", "content": prompt}])
    if seed is not None:
        kwargs["seed"] = seed  # not every server supports it; remove if rejected
    r = _client.chat.completions.create(**kwargs)
    return (r.choices[0].message.content or "").strip(), r.model
Temperature 0 and a seed reduce variation but don't guarantee identical outputs on every provider. Section 8 shows how to measure how much variation remains.
5.4 The runner and the two control baselines
The runner supports two special modes besides real backends. Neither is optional:
none: an empty context. This measures what the answer model can get right without memory, by guessing or from prior knowledge. If this baseline scores well, your questions leak their answers and the dataset needs fixing.oracle: exactly the gold evidence turns. This is the ceiling of the answer-and-judge pipeline. If even the oracle scores poorly, the problem is in the prompt, the answer model or the judge, and comparing memory systems is pointless until it is fixed.
run.py:
import argparse
import json
import time

import yaml

from backends import load_backend
from context import build_context
from interface import Hit, MemoryItem
from llm import complete


def session_items(session):
    for t in session["turns"]:
        yield MemoryItem(item_id=t["turn_id"], text=f'{t["role"]}: {t["text"]}',
                         metadata={"session_id": session["session_id"],
                                   "timestamp": session["timestamp"],
                                   "role": t["role"]})


def provenance(hits):
    # None means "not measurable": at least one hit has no source ids.
    if any(not h.source_ids for h in hits):
        return None
    return [sid for h in hits for sid in h.source_ids]


def main():
    ap = argparse.ArgumentParser()
    ap.add_argument("--config", required=True)
    ap.add_argument("--backend", required=True)  # keyword | http | none | oracle
    ap.add_argument("--out", required=True)
    a = ap.parse_args()

    cfg = yaml.safe_load(open(a.config, encoding="utf-8"))
    cases = [json.loads(l) for l in open(cfg["dataset"], encoding="utf-8") if l.strip()]
    special = a.backend in ("none", "oracle")
    backend = None if special else load_backend(a.backend, cfg)
    name = a.backend if special else backend.name
    version = "-" if special else backend.version

    with open(a.out, "w", encoding="utf-8") as out:
        for case in cases:
            ns = f'{cfg["run_id"]}-{case["case_id"]}'
            by_id = {}
            for s in case["sessions"]:
                for it in session_items(s):
                    by_id[it.item_id] = it

            ingest_s = None
            if backend:
                backend.reset(ns)
                t0 = time.perf_counter()
                for s in case["sessions"]:  # one Add per session, chronological
                    backend.add(ns, list(session_items(s)))
                backend.flush(ns, cfg["flush_timeout_s"])
                ingest_s = round(time.perf_counter() - t0, 3)

            for q in case["questions"]:
                search_ms = None
                if a.backend == "none":
                    hits = []
                elif a.backend == "oracle":
                    hits = [Hit(text=by_id[i].text, score=1.0, source_ids=(i,),
                                timestamp=by_id[i].metadata["timestamp"])
                            for i in q["evidence"]]
                else:
                    t1 = time.perf_counter()
                    hits = backend.search(ns, q["question"], cfg["top_k"])
                    search_ms = round((time.perf_counter() - t1) * 1000, 1)

                context, kept, used = build_context(hits, cfg["context_token_budget"])
                prompt = cfg["answer_prompt"].format(
                    asked_at=q["asked_at"], question=q["question"],
                    context=context or "(no memories)")
                answer, served_model = complete(
                    cfg["answer_model"], prompt, temperature=0.0,
                    seed=cfg["seed"], max_tokens=cfg["answer_max_tokens"])

                out.write(json.dumps({
                    "run_id": cfg["run_id"], "backend": name,
                    "backend_version": version, "case_id": case["case_id"],
                    "qid": q["qid"], "type": q["type"],
                    "question": q["question"], "asked_at": q["asked_at"],
                    "gold_answer": q["gold_answer"], "evidence": q["evidence"],
                    "retrieved_ids": provenance(hits),
                    "context_ids": provenance(kept),
                    "context_tokens": used, "answer": answer,
                    "served_model": served_model,
                    "ingest_s": ingest_s, "search_ms": search_ms,
                }, ensure_ascii=False) + "\n")


if __name__ == "__main__":
    main()
Three design decisions in this file matter for fairness:
- One
Addper session, in chronological order. Systems that extract or merge facts behave differently when they get one turn at a time, one session at a time, or everything at once. Choose one granularity for all of them. Session-level is a reasonable default because that's how a real agent usually commits memory. - The query is the raw question. No system gets a rewritten query. If you want to test query rewriting, add it as a stage of the harness that every system shares.
- Two recall measurements.
retrieved_idsis whatSearchreturned.context_idsis what actually fit in the budget. A system whose results are verbose can find the evidence and still lose it to truncation, and you want to see that difference.
The interface also has a limitation. search doesn't receive asked_at, so systems that use time-aware ranking can't use the question date. This keeps the interface minimal, and it is the same for everyone. If time awareness is central to your use case, extend the interface with a now parameter and pass it to every system.
6. One evaluation procedure
Scoring is where comparisons quietly drift apart. Use one procedure with three layers:
- Deterministic match first. If the normalized answer equals the normalized gold answer, it is correct, and no model is involved.
- LLM judge for the rest, with a strict rubric. The judge sees only the question, the gold answer and the candidate answer. It never sees the system name, the retrieved context or the other systems' answers.
- Human audit of a random sample, to measure how often the judge agrees with a person.
judge.py:
import argparse
import json
import random
import re
import unicodedata

import yaml

from llm import complete

JUDGE_PROMPT = """You grade one answer against a reference answer.

Question: {question}
Reference answer: {gold}
Candidate answer: {answer}

Rules:
- "correct" if the candidate states the same fact as the reference; harmless extra detail is fine.
- "incorrect" if it states a different or outdated fact, or hedges between several options.
- If the reference is "I don't know", the candidate is correct only if it declines to answer.

Return only JSON: {{"verdict": "correct"}} or {{"verdict": "incorrect"}}"""


def norm(s: str) -> str:
    s = unicodedata.normalize("NFKC", s).lower()
    s = re.sub(r"[^\w\s]", " ", s)
    return " ".join(s.split())


def judge_one(question, gold, answer, cfg):
    if norm(gold) and norm(gold) == norm(answer):
        return {"verdict": "correct", "by": "exact"}
    raw, served = complete(cfg["judge_model"],
                           JUDGE_PROMPT.format(question=question, gold=gold,
                                               answer=answer),
                           temperature=0.0, seed=cfg["seed"], max_tokens=30)
    try:
        verdict = json.loads(raw)["verdict"]
    except (json.JSONDecodeError, KeyError, TypeError):
        verdict = "unparseable"
    return {"verdict": verdict, "by": "llm", "judge_served_model": served}


def main():
    ap = argparse.ArgumentParser()
    ap.add_argument("--config", required=True)
    ap.add_argument("--runs", nargs="+", required=True)
    ap.add_argument("--out", required=True)
    a = ap.parse_args()
    cfg = yaml.safe_load(open(a.config, encoding="utf-8"))

    records = [json.loads(l) for p in a.runs
               for l in open(p, encoding="utf-8") if l.strip()]
    # Interleave all systems so judge drift over time cannot favour one of them.
    random.Random(cfg["seed"]).shuffle(records)

    with open(a.out, "w", encoding="utf-8") as out:
        for r in records:
            v = judge_one(r["question"], r["gold_answer"], r["answer"], cfg)
            out.write(json.dumps({"backend": r["backend"], "qid": r["qid"], **v},
                                 ensure_ascii=False) + "\n")


if __name__ == "__main__":
    main()
Guidelines for the judge:
- Prefer a judge model different from the answer model. A model grading its own answers may share their blind spots. Whatever you choose, use the same judge for every system.
- Count
unparseableas incorrect and report how many there were. If one system's answers produce many more unparseable verdicts than the others, look at those answers manually. - Treat "abstention" carefully. A system that always says "I don't know" gets every abstention question right and fails everything else. That is why the results are reported per question type, never only as one total.
6.1 Human audit of the judge
Pull a random sample of verdicts, around 50 to 100, and label them yourself without looking at the judge's verdict or the system name:
python - <<'EOF'
import json, random
v = [json.loads(l) for l in open("results/verdicts.jsonl", encoding="utf-8")]
recs = {}
import glob
for p in glob.glob("runs/*.jsonl"):
    for l in open(p, encoding="utf-8"):
        r = json.loads(l); recs[(r["backend"], r["qid"])] = r
sample = random.Random(11).sample(v, min(80, len(v)))
with open("results/audit.jsonl", "w", encoding="utf-8") as out:
    for i, s in enumerate(sample):
        r = recs[(s["backend"], s["qid"])]
        out.write(json.dumps({"audit_id": i, "question": r["question"],
                              "gold": r["gold_answer"], "answer": r["answer"],
                              "human_verdict": None}, ensure_ascii=False) + "\n")
EOF
Fill in human_verdict, then join the file back by audit_id (keep the mapping to backend and qid in a separate file the labeler doesn't open). Report the agreement rate. If the judge disagrees with you noticeably more often for one system than for others, the judge is not neutral for this dataset. Tighten the rubric before reading anything into the scores.
7. Scoring with paired statistics
All systems answer the same questions, so compare them pairwise, question by question, not by subtracting two averages. Questions within one case aren't independent: if a case is hard for one reason, all its questions tend to fail together. So the confidence interval resamples cases, not individual questions. This is a cluster bootstrap.
score.py:
import argparse
import json
import random
from collections import defaultdict


def load(path):
    return [json.loads(l) for l in open(path, encoding="utf-8") if l.strip()]


def mean(xs):
    xs = list(xs)
    return sum(xs) / len(xs) if xs else float("nan")


def cluster_bootstrap(diff_by_case, n=10000, seed=0):
    rng = random.Random(seed)
    cases = list(diff_by_case)
    point = mean(d for c in cases for d in diff_by_case[c])
    stats = []
    for _ in range(n):
        pick = [rng.choice(cases) for _ in cases]
        stats.append(mean(d for c in pick for d in diff_by_case[c]))
    stats.sort()
    return point, stats[int(0.025 * n)], stats[int(0.975 * n) - 1]


def main():
    ap = argparse.ArgumentParser()
    ap.add_argument("--runs", nargs="+", required=True)
    ap.add_argument("--verdicts", required=True)
    ap.add_argument("--baseline", required=True)
    a = ap.parse_args()

    ok = {(v["backend"], v["qid"]): v["verdict"] == "correct"
          for v in load(a.verdicts)}
    runs = defaultdict(dict)
    for p in a.runs:
        for r in load(p):
            runs[r["backend"]][r["qid"]] = r

    print("backend | n | accuracy | recall_any@k | recall_all(ctx) | by type")
    for b, recs in sorted(runs.items()):
        acc = mean(ok[(b, q)] for q in recs)
        ev = [r for r in recs.values() if r["evidence"]]
        meas = [r for r in ev if r["retrieved_ids"] is not None
                and r["context_ids"] is not None]
        r_any = mean(bool(set(r["retrieved_ids"]) & set(r["evidence"]))
                     for r in meas) if meas else None
        r_all = mean(set(r["evidence"]) <= set(r["context_ids"])
                     for r in meas) if meas else None
        types = defaultdict(list)
        for q, r in recs.items():
            types[r["type"]].append(ok[(b, q)])
        by_type = ", ".join(f"{t}={mean(v):.2f}(n={len(v)})"
                            for t, v in sorted(types.items()))
        fmt = lambda x: "n/a" if x is None else f"{x:.2f}"
        print(f"{b} | {len(recs)} | {acc:.2f} | {fmt(r_any)} | {fmt(r_all)} | {by_type}")

    base = runs[a.baseline]
    print(f"\npaired difference vs {a.baseline} (cluster bootstrap over cases, 95% CI)")
    for b, recs in sorted(runs.items()):
        if b == a.baseline:
            continue
        common = sorted(set(base) & set(recs))
        diff = defaultdict(list)
        for q in common:
            diff[recs[q]["case_id"]].append(int(ok[(b, q)]) - int(ok[(a.baseline, q)]))
        point, lo, hi = cluster_bootstrap(diff)
        print(f"{b}: {point:+.3f}  [{lo:+.3f}, {hi:+.3f}]  over {len(common)} questions")


if __name__ == "__main__":
    main()
Read the output like this. When the interval for "B minus A" includes zero, this dataset doesn't separate the two systems, whatever the averages say. With 150 questions, intervals several points wide are normal. That's a property of small test sets, and it's why you should report the interval instead of hiding it.
8. Running it end to end
8.1 Setup
python -m venv .venv && . .venv/bin/activate
pip install openai pyyaml requests
export LLM_API_KEY=...        # never commit; never paste into run files
# export LLM_BASE_URL=...     # only for a non-default OpenAI-compatible endpoint
# export MEMORY_API_KEY=...   # only for the http adapter
mkdir -p runs results
8.2 Write a manifest before the run
A result without a manifest can't be reproduced. manifest.py:
import hashlib
import json
import platform
import subprocess
import sys
import time

import yaml


def sha256(path):
    return hashlib.sha256(open(path, "rb").read()).hexdigest()


cfg_path = sys.argv[1]
cfg = yaml.safe_load(open(cfg_path, encoding="utf-8"))
freeze = subprocess.run([sys.executable, "-m", "pip", "freeze"],
                        capture_output=True, text=True).stdout
manifest = {
    "run_id": cfg["run_id"],
    "started_at": time.strftime("%Y-%m-%dT%H:%M:%SZ", time.gmtime()),
    "git_commit": subprocess.run(["git", "rev-parse", "HEAD"],
                                 capture_output=True, text=True).stdout.strip(),
    "dataset_sha256": sha256(cfg["dataset"]),
    "config_sha256": sha256(cfg_path),
    "python": platform.python_version(),
    "pip_freeze_sha256": hashlib.sha256(freeze.encode()).hexdigest(),
    "answer_model": cfg["answer_model"],
    "judge_model": cfg["judge_model"],
    "top_k": cfg["top_k"],
    "context_token_budget": cfg["context_token_budget"],
    "notes": "record backend versions, internal extractor models and any fixed flush delays here",
}
json.dump(manifest, open(f'results/manifest-{cfg["run_id"]}.json', "w"), indent=2)
print(json.dumps(manifest, indent=2))
8.3 Run order
python manifest.py config.yaml

# 1. Controls first: they validate the harness, not the memory systems.
python run.py --config config.yaml --backend none    --out runs/none.jsonl
python run.py --config config.yaml --backend oracle  --out runs/oracle.jsonl

# 2. Reference backend, then systems under test.
python run.py --config config.yaml --backend keyword --out runs/keyword.jsonl
python run.py --config config.yaml --backend http    --out runs/system-under-test.jsonl

# 3. Judge everything together, blinded and shuffled.
python judge.py --config config.yaml --runs runs/*.jsonl --out results/verdicts.jsonl

# 4. Score against the reference backend.
python score.py --runs runs/*.jsonl --verdicts results/verdicts.jsonl --baseline keyword
Keep results/ separate from runs/. Otherwise the runs/*.jsonl glob picks up the verdict file and the scripts read it as a run.
9. Verification: is the test itself working?
Before you look at the comparison, check the harness. Each check below is something you run and look at, not something to assume.
9.1 Control baselines are where they should be
noneshould score low on everything except abstention, where an empty context should produce "I don't know". If it answers factual questions correctly, the gold answers can be guessed. Rewrite those questions with arbitrary specifics (version numbers, internal names, dates).oracleshould score high on all types. Where it doesn't, read its wrong answers. You'll usually find a prompt that can't handle date arithmetic, a gold answer phrased in a way the judge rejects, or evidence lists that are incomplete.- Every real system should fall between
noneandoracle. A system above the oracle is possible, for example when it adds useful context that the gold evidence list missed. Treat it as a signal to audit the evidence labels, not as a win.
9.2 Retrieval is deterministic where it should be
Run the keyword backend twice and compare what it retrieved. The output must be identical:
python run.py --config config.yaml --backend keyword --out runs-check/keyword-2.jsonl
diff <(jq -c '[.qid, .retrieved_ids]' runs/keyword.jsonl) \
     <(jq -c '[.qid, .retrieved_ids]' runs-check/keyword-2.jsonl) && echo "retrieval identical"
Put the rerun in a separate directory so it doesn't enter the scoring glob. For external systems, nondeterministic retrieval isn't necessarily a bug (approximate indexes, background merging), but it is noise. Measure how often the retrieved IDs differ between two runs and report that rate.
9.3 Answer and judge noise is measured
Run the full pipeline for one system twice with an identical config. Score both runs and compute the paired difference with score.py, after renaming the backend field in the second run, for example to keyword-rerun. The interval for the "system versus itself" difference is your noise floor. A difference between two systems that is no larger than that floor tells you nothing.
9.4 Indexing lag is ruled out
Run a system once with its normal flush and once with an extra fixed wait after flush, say 30 seconds. If accuracy or recall changes, flush isn't actually waiting for readiness, and the earlier results understate the system.
9.5 The judge is audited
Report the human-agreement rate from section 6.1, overall and per system.
10. Reporting template
Publish the table together with the manifest. The cells below are deliberately empty. Fill them from your own score.py output and don't copy numbers from anywhere else.
| System (version, internal model) | Accuracy | Δ vs reference [95% CI] | recall_any@k | recall_all in context | Abstention | Knowledge update | Median search ms |
|---|---|---|---|---|---|---|---|
| none (control) | — | — | — | — | — | — | — |
| oracle (control) | — | — | — | — | — | — | — |
| keyword-overlap 0.1 (reference) | — | 0 | — | — | — | — | — |
| system-under-test (version, extractor model) | — | — | — or n/a | — or n/a | — | — | — |
Under the table, add: the number of cases and questions, the answer and judge model IDs, top-k and the token budget, the judge-human agreement, the noise floor from section 9.3, and every deviation from the fairness contract. "System X could not report provenance, so recall is n/a" is a perfectly good line in a report.
Latency belongs in the table, but label it honestly. For a hosted system, search_ms includes network round trips from your machine, so it measures "this system from this location", not the system's internal speed.
11. Failure cases and how to recognize them
| Symptom | Likely cause | What to do |
|---|---|---|
none baseline scores well | Questions are answerable from general knowledge | Use invented, specific facts. Remove questions that none gets right |
oracle scores poorly on temporal | Answer model or prompt can't do date arithmetic | Fix this in the shared pipeline for everyone. It isn't a memory problem |
| A system's recall is high but accuracy is low | Evidence is retrieved but cut by the budget, or buried below distractors | Compare retrieved_ids with context_ids, then check the rank of the evidence |
| Knowledge-update questions answered with the old value | Ranking ignores recency. Timestamps are missing from the context | Check that Hit.timestamp is filled. Note in the report whether the system stores time at all |
| Results change between identical runs | Nondeterministic retrieval, provider-side sampling, moving model alias | Measure the noise floor and pin model IDs. Record served_model |
| First questions of each case fail more often | Indexing not finished when search starts | Fix flush, then rerun the test from section 9.4 |
Many unparseable verdicts | Judge adds prose around the JSON | Tighten the judge prompt or use the provider's JSON mode, the same way for all systems |
| Leftover memories from a previous run show up | reset doesn't delete, or namespaces collide | Change run_id for each run. Verify reset by searching an empty namespace |
| Very high abstention score, low everything else | System returns nothing useful and the model declines | Always read the per-type breakdown, never only the total |
| Rate-limit errors in the middle of a run | Too many parallel calls to an API | Add retries with backoff in the adapter. Rerun failed cases, not the whole set, and log them |
12. Limitations of this method
- It measures memory as seen through one answer model. A system that returns information which helps a stronger model but confuses a weaker one will rank differently with a different model. If the choice of model matters to you, repeat the whole comparison with a second answer model and report both, rather than mixing them.
- The minimal interface hides features. Filters, metadata queries, time-aware search and memory editing aren't exercised. A system that is strong at those can look ordinary here. Extend the interface for everyone if you need them.
- Synthetic data isn't your production traffic. Written test cases are cleaner than real conversations. Before you choose a system for production, repeat the test on anonymized, consented samples of your own data. Remove personal data before it goes into any test file or external service.
- Session-level ingestion is one choice among several. Systems tuned for turn-by-turn streaming may do better with other granularity. You fixed it so the comparison would be fair, not to find the best setting for each system.
- Cost is not normalized. Ingestion with an internal LLM spends tokens that a plain index doesn't. Record call counts and token usage from provider dashboards or logs if cost is part of the decision. This harness doesn't capture them automatically.
- An LLM judge is a measuring instrument with its own error. The human audit tells you how big that error is on your data. It doesn't remove it.
- Small datasets give wide intervals. That's an honest outcome, not a failure. "We can't tell these two apart on 150 questions" is a valid conclusion.
13. Checklist before you publish a comparison
- Fairness contract written and attached.
- Dataset hash, config hash, git commit and model IDs in the manifest.
noneandoraclecontrols run and within the expected range.- Every system ingested through the same
Addsequence and queried only throughSearch. - Same top-k, token budget, answer prompt and answer model for all systems.
- Judge blinded to the system name, records shuffled across systems, human agreement reported.
- Paired differences with cluster-bootstrap intervals and a measured noise floor.
- Per-type breakdown shown, with abstention reported separately.
- Every deviation (no provenance, fixed flush delay, internal extractor model) stated in plain words.
- No API keys, personal data or customer facts in runs, logs or the published report.
The method fits in a sentence: change only the memory, measure retrieval and answers separately, check your instruments before you trust them, and report the uncertainty along with the averages. Comparisons built this way tend to show smaller differences than marketing tables do, and those differences hold up when someone else repeats the test.
For related setups, see the practical guides. For the terms used in this article, see the glossary.