Reproducible Multi-Agent Scenarios and Property-Based Testing
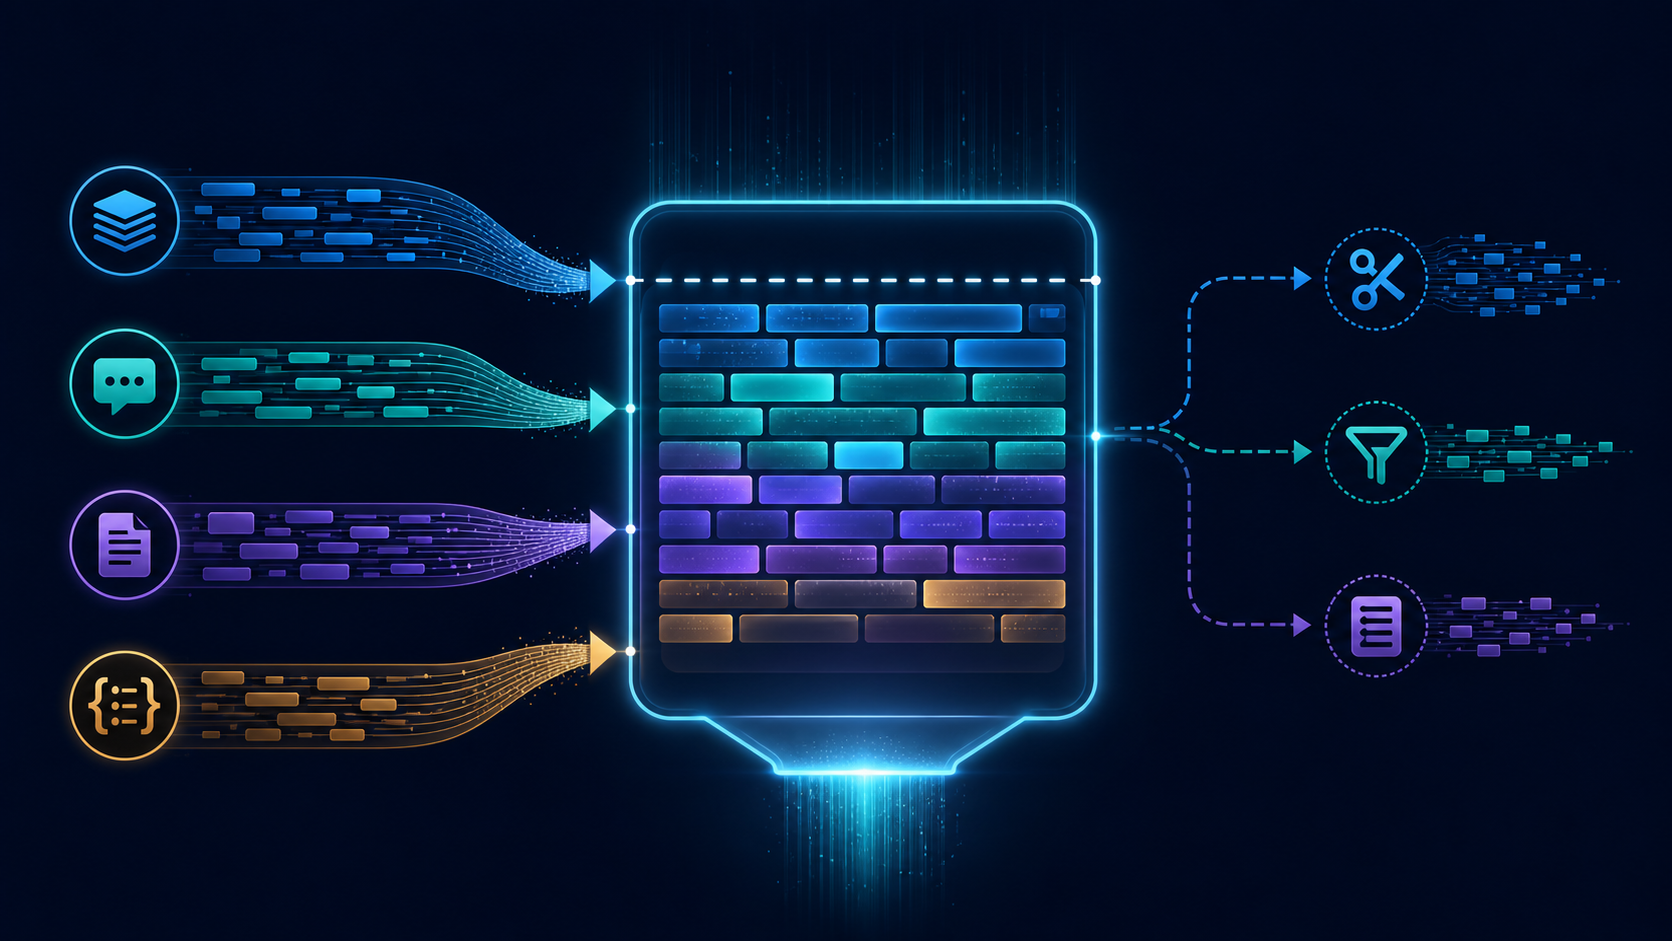
Randomized multi-agent demos are useful for discovery, but they are poor evidence when the same input can produce a different event sequence on every run. This article develops a deterministic scenario engine, makes randomness explicit, and verifies behavior with property-based testing and invariants.
The problem: a plausible run is not a reproducible result
A multi-agent demonstration usually has a story: several agents receive a task, exchange messages, make decisions, and produce an outcome. The story becomes difficult to trust when it depends on hidden randomness, wall-clock time, unordered iteration, or an external service that changes between runs.
Suppose an orchestrator assigns work to three agents. One run finishes in six turns. Another takes nine. A third produces the same final answer but uses a different allocation path. Without a complete record of the inputs and choices, it is hard to tell whether the differences are expected variation, a regression, or a formula error.
The practical target is not “make every agent intelligent in exactly the same way.” The target is narrower and more useful:
- the same scenario specification and seed produce the same observable trace;
- the trace can be saved, inspected, and replayed;
- system rules are expressed as executable invariants;
- generated scenarios search for edge cases that hand-written examples miss;
- failures identify a seed and a minimal scenario rather than only reporting “flaky.”
A small concrete case
Consider a dispatch simulation. A coordinator receives jobs and assigns each job to one of several workers. Each worker has a capacity. Jobs have a positive workload. The coordinator may use a randomized tie-breaker when workers have equal remaining capacity.
The example has four observable rules:
- every job is assigned at most once;
- an assignment never exceeds the worker’s remaining capacity;
- the sum of assigned workload equals the sum of completed job workload;
- given the same scenario and seed, the event trace is identical.
The fourth rule is a reproducibility property. The first three are domain invariants. Keeping them separate matters: a run can be deterministic and still be wrong, or correct for one input while remaining nondeterministic.
Scenario input
{
  "seed": 184467,
  "workers": [
    {"id": "w0", "capacity": 7},
    {"id": "w1", "capacity": 5},
    {"id": "w2", "capacity": 4}
  ],
  "jobs": [
    {"id": "j0", "work": 3},
    {"id": "j1", "work": 2},
    {"id": "j2", "work": 4},
    {"id": "j3", "work": 1}
  ]
}
This is an example fixture, not a measured production workload. Its purpose is to make the state transition and its checks easy to inspect.
Design the deterministic boundary first
A reproducible engine starts by making all sources of variation visible. The engine should receive or construct these dependencies explicitly:
- a seed or a random-number generator instance;
- an explicit input order for workers and jobs;
- a clock abstraction, if time affects behavior;
- an event sink that records decisions;
- stable serialization for scenario and trace data.
Do not call a process-global random function from deep inside an agent. That creates an invisible dependency. Do not use the current time as an implicit tie-breaker. Do not rely on a hash-map iteration order unless the runtime contract makes that order part of the design.
One random stream, one owner
A useful first rule is that the scenario runner owns the random stream. Agents may ask for a random decision through a narrow interface, but they should not create their own unseeded generator.
from dataclasses import dataclass
import random
from typing import Any

@dataclass(frozen=True)
class Job:
    id: str
    work: int

@dataclass
class Worker:
    id: str
    capacity: int
    remaining: int

@dataclass(frozen=True)
class Event:
    kind: str
    payload: dict[str, Any]

class Scenario:
    def __init__(self, seed: int):
        self.seed = seed
        self.rng = random.Random(seed)
        self.events: list[Event] = []

    def record(self, kind: str, **payload: Any) -> None:
        self.events.append(Event(kind=kind, payload=payload))

    def choose(self, values: list[str]) -> str:
        if not values:
            raise ValueError("cannot choose from an empty list")
        return self.rng.choice(values)
Python’s local generator is sufficient for this example because the generator is created from an explicit seed and is used by one scenario. The reproducibility guarantee still depends on using a fixed runtime and preserving the same sequence of random calls.
Stable ordering is part of the input
A seed does not compensate for an unstable candidate list. If the list passed to choice changes order, the same random index can select a different worker. Normalize ordering at the boundary:
def ordered_workers(raw_workers: list[dict]) -> list[Worker]:
    workers = [
        Worker(
            id=item["id"],
            capacity=item["capacity"],
            remaining=item["capacity"],
        )
        for item in raw_workers
    ]
    return sorted(workers, key=lambda worker: worker.id)
Whether sorting is the right domain rule depends on the application. The important point is that the rule is explicit. If input order is meaningful, preserve it and record it. If it is not meaningful, canonicalize it.
Build the smallest useful engine
The engine below assigns jobs one at a time. It first computes feasible workers, then chooses among them using the scenario-owned random stream. Every state-changing decision emits an event.
def run_dispatch(
    seed: int,
    raw_workers: list[dict],
    raw_jobs: list[dict],
) -> list[dict]:
    scenario = Scenario(seed)
    workers = ordered_workers(raw_workers)
    jobs = [
        Job(id=item["id"], work=item["work"])
        for item in sorted(raw_jobs, key=lambda item: item["id"])
    ]

    scenario.record(
        "scenario_started",
        seed=seed,
        workers=[worker.id for worker in workers],
        jobs=[job.id for job in jobs],
    )

    assigned: set[str] = set()

    for job in jobs:
        feasible = [
            worker for worker in workers
            if worker.remaining >= job.work
        ]

        if not feasible:
            scenario.record(
                "job_rejected",
                job_id=job.id,
                work=job.work,
                reason="no_capacity",
            )
            continue

        candidates = [worker.id for worker in feasible]
        selected_id = scenario.choose(candidates)
        selected = next(
            worker for worker in feasible
            if worker.id == selected_id
        )

        selected.remaining -= job.work
        assigned.add(job.id)

        scenario.record(
            "job_assigned",
            job_id=job.id,
            worker_id=selected.id,
            work=job.work,
            remaining=selected.remaining,
        )

    scenario.record(
        "scenario_finished",
        assigned=sorted(assigned),
        remaining={
            worker.id: worker.remaining
            for worker in workers
        },
    )

    return [
        {"kind": event.kind, "payload": event.payload}
        for event in scenario.events
    ]
This implementation deliberately favors traceability over abstraction. A production engine may have richer agent policies, message queues, retries, and asynchronous scheduling. The same boundary principles still apply: explicit dependencies, stable inputs, and observable transitions.
Define invariants as executable checks
An invariant is a condition that must remain true for every valid state or completed trace. It is stronger than checking one expected output because it describes a class of acceptable outcomes.
For this example, the trace is the source of evidence. The checker reconstructs assignments from events and compares them with the declared inputs.
def check_dispatch_invariants(
    raw_workers: list[dict],
    raw_jobs: list[dict],
    trace: list[dict],
) -> None:
    jobs = {
        item["id"]: item["work"]
        for item in raw_jobs
    }
    capacities = {
        item["id"]: item["capacity"]
        for item in raw_workers
    }

    assignments = [
        event["payload"]
        for event in trace
        if event["kind"] == "job_assigned"
    ]

    assigned_ids = [item["job_id"] for item in assignments]

    assert len(assigned_ids) == len(set(assigned_ids)), (
        "a job was assigned more than once"
    )

    used_by_worker: dict[str, int] = {}

    for item in assignments:
        job_id = item["job_id"]
        worker_id = item["worker_id"]
        work = item["work"]

        assert job_id in jobs, "trace references an unknown job"
        assert worker_id in capacities, "trace references an unknown worker"
        assert work == jobs[job_id], "trace changed the job workload"

        used_by_worker[worker_id] = (
            used_by_worker.get(worker_id, 0) + work
        )

    for worker_id, used in used_by_worker.items():
        assert used <= capacities[worker_id], (
            f"worker {worker_id} exceeded capacity"
        )

    assigned_work = sum(item["work"] for item in assignments)
    completed_work = sum(jobs[job_id] for job_id in assigned_ids)

    assert assigned_work == completed_work, (
        "assigned work does not match completed work"
    )
The assertions above check consistency between the event trace and the input. They do not prove that the dispatch policy is optimal, fair, or appropriate for a real operation. Those are separate properties requiring separate definitions.
Make reproducibility a first-class test
The most direct reproducibility check runs the same scenario twice and compares canonical traces.
import json

def canonical(value: object) -> str:
    return json.dumps(
        value,
        sort_keys=True,
        separators=(",", ":"),
    )

def test_same_seed_replays_same_trace() -> None:
    workers = [
        {"id": "w0", "capacity": 7},
        {"id": "w1", "capacity": 5},
        {"id": "w2", "capacity": 4},
    ]
    jobs = [
        {"id": "j0", "work": 3},
        {"id": "j1", "work": 2},
        {"id": "j2", "work": 4},
        {"id": "j3", "work": 1},
    ]

    first = run_dispatch(184467, workers, jobs)
    second = run_dispatch(184467, workers, jobs)

    assert canonical(first) == canonical(second)
A useful companion test checks that changing the seed is allowed to change the trace. It should not require a difference for every input: some scenarios have only one feasible choice. The correct property is that the engine does not claim seed independence when alternatives exist.
def assigned_worker_ids(trace: list[dict]) -> list[str]:
    return [
        event["payload"]["worker_id"]
        for event in trace
        if event["kind"] == "job_assigned"
    ]

def test_seed_can_select_different_valid_paths() -> None:
    workers = [
        {"id": "w0", "capacity": 3},
        {"id": "w1", "capacity": 3},
    ]
    jobs = [{"id": "j0", "work": 1}]

    traces = {
        canonical(run_dispatch(seed, workers, jobs))
        for seed in range(32)
    }

    # This is a diagnostic expectation for this fixture, not a
    # universal property of every dispatch problem.
    assert len(traces) > 1
Property-based testing: test families, not anecdotes
Hand-written examples are valuable because they explain intent. They are weak at exploring combinations: empty inputs, duplicate identifiers, capacity boundaries, unusually large workloads, and many possible assignment orders.
Property-based testing generates many inputs and checks a property for each one. When a property fails, the framework attempts to shrink the input to a smaller counterexample. That counterexample is often more useful than a long random trace because it exposes the smallest combination that violates the rule.
The following example uses Hypothesis. The command is a reproducible setup instruction; it is not a claim that the command has been executed here.
python -m pip install hypothesis pytest
pytest -q
Generating valid scenarios
Start with generators that produce valid identifiers and non-negative capacities. The first property should cover conservation and uniqueness, not policy quality.
from hypothesis import given, strategies as st

def worker_strategy():
    return st.fixed_dictionaries({
        "id": st.text(
            alphabet=st.characters(
                whitelist_categories=("Ll", "Nd")
            ),
            min_size=1,
            max_size=4,
        ),
        "capacity": st.integers(min_value=0, max_value=20),
    })

def job_strategy():
    return st.fixed_dictionaries({
        "id": st.text(
            alphabet=st.characters(
                whitelist_categories=("Ll", "Nd")
            ),
            min_size=1,
            max_size=4,
        ),
        "work": st.integers(min_value=0, max_value=10),
    })

def unique_records(strategy, key: str, max_size: int = 8):
    return st.lists(
        strategy,
        min_size=0,
        max_size=max_size,
    ).map(
        lambda records: list({
            record[key]: record for record in records
        }.values())
    )

scenario_inputs = st.fixed_dictionaries({
    "workers": unique_records(worker_strategy(), "id"),
    "jobs": unique_records(job_strategy(), "id"),
    "seed": st.integers(min_value=0, max_value=2**32 - 1),
})
The generator above intentionally permits zero capacity and zero workload. Whether those values are valid depends on the domain. If they are invalid, reject them in the strategy or add a separate negative-input test. Do not silently assume that a generator’s domain matches the application’s domain.
Checking the invariant across generated scenarios
@given(scenario_inputs)
def test_generated_scenarios_preserve_invariants(case):
    trace = run_dispatch(
        seed=case["seed"],
        raw_workers=case["workers"],
        raw_jobs=case["jobs"],
    )

    check_dispatch_invariants(
        raw_workers=case["workers"],
        raw_jobs=case["jobs"],
        trace=trace,
    )

@given(scenario_inputs)
def test_generated_scenarios_are_replayable(case):
    first = run_dispatch(
        seed=case["seed"],
        raw_workers=case["workers"],
        raw_jobs=case["jobs"],
    )
    second = run_dispatch(
        seed=case["seed"],
        raw_workers=case["workers"],
        raw_jobs=case["jobs"],
    )

    assert canonical(first) == canonical(second)
These tests say something precise: for every generated case accepted by the strategy, the trace satisfies the stated invariants and repeats under the same seed. They do not say that the engine is correct for inputs outside the strategy, that the random generator is stable across all Python versions, or that the policy is fair.
Test formulas independently from orchestration
Formula errors often hide inside apparently successful scenarios. A worker may report remaining capacity that looks plausible while violating conservation by one unit. Put arithmetic in small pure functions and test the functions directly.
def remaining_capacity(capacity: int, assigned_work: list[int]) -> int:
    if capacity < 0:
        raise ValueError("capacity must be non-negative")
    if any(work < 0 for work in assigned_work):
        raise ValueError("work must be non-negative")

    remaining = capacity - sum(assigned_work)

    if remaining < 0:
        raise ValueError("capacity exceeded")

    return remaining
The useful properties include conservation, monotonicity, and boundary behavior:
@given(
    st.integers(min_value=0, max_value=100),
    st.lists(
        st.integers(min_value=0, max_value=10),
        max_size=10,
    ),
)
def test_remaining_capacity_conserves_work(capacity, parts):
    total = sum(parts)
    if total <= capacity:
        result = remaining_capacity(capacity, parts)
        assert result + total == capacity

@given(
    st.integers(min_value=0, max_value=100),
    st.lists(
        st.integers(min_value=0, max_value=10),
        max_size=10,
    ),
    st.integers(min_value=0, max_value=10),
)
def test_remaining_capacity_does_not_increase_after_more_work(
    capacity,
    parts,
    extra,
):
    before_total = sum(parts)
    if before_total + extra <= capacity:
        before = remaining_capacity(capacity, parts)
        after = remaining_capacity(capacity, parts + [extra])
        assert after <= before
Keep formula tests close to the formula. An end-to-end test may detect the symptom, but a small property test usually makes the defect easier to localize.
Trace format and replay
A useful trace contains enough information to explain a decision without exposing secrets or unnecessary personal data. For the example, that means event type, stable identifiers, workloads, remaining capacity, and the seed. It does not require prompts, credentials, private messages, or raw customer records.
{
  "schema_version": 1,
  "seed": 184467,
  "input_hash": "computed-by-the-runner",
  "events": [
    {
      "kind": "scenario_started",
      "payload": {
        "workers": ["w0", "w1", "w2"],
        "jobs": ["j0", "j1", "j2", "j3"]
      }
    },
    {
      "kind": "job_assigned",
      "payload": {
        "job_id": "j0",
        "worker_id": "w1",
        "work": 3,
        "remaining": 2
      }
    }
  ]
}
The hash field is a placeholder for a value computed by the runner. Do not copy a fabricated digest into a real fixture. In a working implementation, canonicalize the input first, then hash the canonical bytes with the algorithm selected by the project.
Replay should validate the input hash before executing. If the scenario definition changed, report a mismatch rather than presenting a new trace as a replay of the old one.
def replay(seed, workers, jobs, expected_trace):
    actual_trace = run_dispatch(seed, workers, jobs)

    if canonical(actual_trace) != canonical(expected_trace):
        raise AssertionError(
            "replay mismatch: compare the first differing event"
        )

    return actual_trace
Failure cases worth designing for
Hidden randomness
Symptom: repeated runs differ even though the seed is unchanged.
Likely cause: an agent, helper, library, or external service uses another random source.
Response: inventory random calls, inject the generator, and record decisions at the boundary.
Unstable iteration
Symptom: the same choices appear to be available, but a different worker is selected.
Likely cause: candidate order depends on an unordered collection or concurrent completion order.
Response: define a stable ordering or record the ordering as part of the scenario input.
Clock-dependent behavior
Symptom: a timeout, expiry, or scheduled action changes between runs.
Likely cause: code reads wall-clock time directly.
Response: inject a clock and use a fixed time in tests. If elapsed time matters, use a controlled monotonic clock.
Concurrency races
Symptom: event order changes even with identical inputs and seed.
Likely cause: scheduling order is uncontrolled.
Response: separate logical decisions from execution scheduling, or make the scheduler deterministic in the test harness. If nondeterminism is a real system property, test order-independent invariants rather than asserting one exact trace.
Overly strict snapshots
Symptom: harmless metadata changes break every fixture.
Likely cause: the snapshot contains volatile fields such as timestamps or generated identifiers.
Response: canonicalize and exclude fields that are not part of the behavior under test.
Invalid generated data
Symptom: property tests fail in input validation rather than in the intended property.
Likely cause: the strategy generates combinations the domain forbids.
Response: decide whether invalid inputs should be rejected, then encode that decision explicitly with valid and invalid strategies.
Verification workflow
A reproducible verification workflow should make failures portable between machines and contributors.
- Record the interpreter or runtime version and dependency lockfile.
- Run deterministic unit tests for formulas and state transitions.
- Run replay tests using committed fixtures.
- Run property-based tests with a fixed test configuration.
- When a generated case fails, save the seed and shrunk input.
- Re-run only the saved counterexample before changing the implementation.
- After a fix, keep the counterexample as a regression fixture.
Example commands for a Python project might look like this:
python --version
python -m pip freeze > verification-environment.txt
pytest -q tests/test_dispatch.py
pytest -q tests/test_properties.py --hypothesis-show-statistics
These commands are examples of a verification record. They are not reported results from this article. A real report should include the command output, the environment, the commit identifier, and any relevant configuration.
What counts as evidence?
A strong result can answer all of these questions:
- Which exact scenario input was tested?
- Which seed and runtime were used?
- Which invariants were checked?
- Was the trace compared byte-for-byte or after canonicalization?
- How many generated examples were completed?
- Can another person replay the failing or representative case?
Avoid replacing these details with broad claims such as “the agents were tested thoroughly.” The latter does not identify a repeatable procedure.
Limitations
Determinism is not the same as realism. A deterministic scheduler can hide production races. A seeded pseudo-random generator is not a model of every possible agent behavior. A passing invariant suite does not establish that an allocation policy is fair, efficient, safe, or suitable for a regulated workflow.
Exact replay can also be sensitive to implementation changes. Changing the random-number algorithm, changing the order of random calls, upgrading a runtime, or modifying serialization can change the trace even when the domain behavior remains acceptable. Treat the trace format and runtime assumptions as versioned interfaces.
For systems that intentionally permit concurrency, prefer a layered strategy: deterministic tests for pure decisions, invariant checks for all valid schedules, controlled schedule exploration for selected races, and a smaller set of integration tests against real services. Each layer answers a different question.
A practical implementation checklist
- Give every scenario an explicit seed.
- Keep random-number generation under scenario ownership.
- Inject clocks, identifiers, and external responses.
- Define stable input and candidate ordering.
- Emit events for state-changing decisions.
- Canonicalize traces before comparison.
- Write invariants for uniqueness, conservation, bounds, and lifecycle states.
- Use generated scenarios to explore valid edge cases.
- Save shrunk counterexamples as regression fixtures.
- Record runtime, dependencies, seed, input, and trace schema.
- Separate deterministic replay tests from order-independent concurrency tests.
- Keep secrets and personal data out of fixtures and traces.
Conclusion
Reproducible Multi-Agent Scenarios and Property-Based Testing becomes practical when reproducibility is treated as an architectural boundary rather than a test-afterthought. Make randomness, time, ordering, and external responses explicit. Record decisions as a stable trace. Express business rules as invariants. Then use generated scenarios to search the spaces that examples do not cover.
The expected result is not a claim that every multi-agent run will be identical forever. It is a system where identical declared inputs can be replayed under declared assumptions, where deviations are visible, and where formula errors fail close to their source.