Почему агентные бенчмарки измеряют модель вместе с оболочкой: why agent benchmarks score the model and its harness together
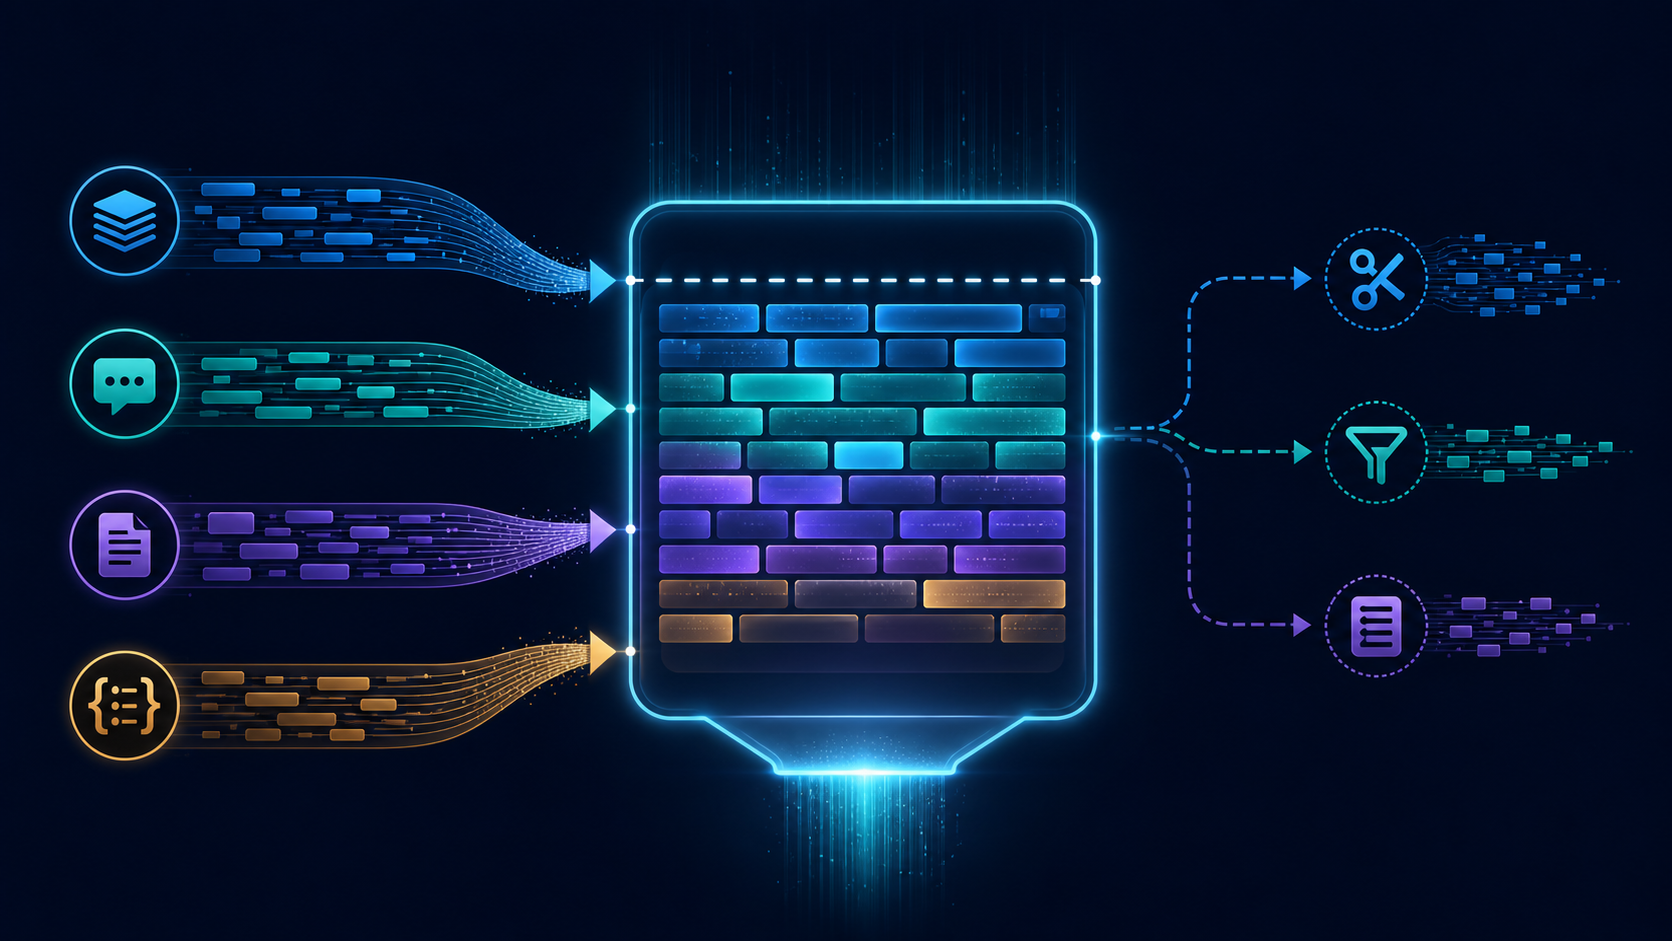
When a leaderboard says “model X solves N% of terminal tasks”, that number does not describe model X on its own. It describes model X running inside one particular agent harness: its prompts, tool set, context management, retry policy, step limit and stopping rule. Change the harness and the same weights can move up or down the ranking. This guide shows how to treat the pair model + harness as the actual unit of measurement and how to build a comparison table that reports quality together with cost, tokens and the number of actions. When you finish, you will have a table you can defend in a design review.
1. The misconception: “the score belongs to the model”
For a single-turn benchmark, such as a multiple-choice exam, it is roughly fair to treat the score as a property of the LLM. The scaffold is thin: one prompt, one answer, one parser. Agent benchmarks are different. In Terminal-Bench, SWE-bench-style suites and similar evaluations, the model does not answer once. It works in a loop. It reads the task, issues a tool call such as a shell command or a file edit, observes the output, decides what to do next, and eventually stops. A verifier then checks the final state of the environment.
Every step of that loop is shaped by code that is not the model:
- What the model sees: the system prompt, the task framing, how terminal output is truncated, and whether earlier turns are summarised when the context window fills up.
- What the model can do: raw keystrokes into a tmux pane, structured “run command” tools, a dedicated file editor, a search tool, or none of these.
- How long it may try: the maximum number of turns, the wall-clock timeout per command and per task, and the token budget.
- How errors are handled: whether malformed tool calls are retried, whether the harness re-prompts after a timeout, and whether it allows self-verification before submitting.
- When it stops: an explicit “task complete” signal, the step limit, or a budget cut-off.
Each of these settings can raise or lower the pass rate. Most of them also change how much the run costs. A harness that lets the model run tests repeatedly may solve more tasks and also spend several times more tokens. A harness that truncates terminal output aggressively may save money and also hide the one error line the model needed to see. The leaderboard number folds all of this into a single scalar.
Well-run public leaderboards already acknowledge this. Terminal-Bench, for example, lists entries as an agent paired with a model rather than as a model alone. In practice, people still read the model column and skip the agent column. The consequences are usually expensive. A team picks a model because of its leaderboard rank, runs it inside its own in-house harness, and gets a different result. It then concludes that the benchmark is broken or that the model “underperforms in production”. Often neither is true. The team measured a different pair.
2. What exactly counts as “the harness”
Before you compare anything, write down what the harness consists of. Two runs differ in harness if any of the following differ. Treat this list as the identity of the harness, in the same way that a model name plus version identifies the model.
| Component | Examples of what varies | Why it moves the score |
|---|---|---|
| Interaction mode | Raw terminal keystrokes vs structured tool calls vs editor tools | Some models format structured calls reliably and struggle with interactive programs such as pagers and REPLs, or the reverse |
| Prompt and framing | System prompt, examples, task wording, explicit planning instructions | Changes strategy: plan first or act first, verify or submit immediately |
| Observation handling | Output truncation length, screen scraping vs captured stdout, ANSI stripping | Decides whether critical error text reaches the model |
| Context management | Full history, sliding window, summarisation, memory files | Long tasks fail differently depending on what is forgotten |
| Budgets | Max turns, per-command timeout, per-task timeout, max output tokens | A higher budget usually trades cost for success; a lower one can turn near-misses into failures |
| Error recovery | Retry on malformed call, re-prompt on timeout, API retry/backoff | Separates model mistakes from transport noise, or fails to |
| Stopping rule | Explicit completion signal, double confirmation, self-test requirement | Premature stopping is a common and harness-sensitive failure |
| Sampling settings | Temperature, reasoning effort or thinking budget, top-p | Often set by the harness, not by the model vendor |
| Environment | Container image, network access, preinstalled tools, CPU and RAM | Strictly part of the benchmark, but harnesses sometimes add tools to it |
Rule of thumb: if you cannot write the harness identity as a pinned commit plus a config file, you cannot reproduce the score, and you should not compare it with anything.
3. A concrete case (illustrative, not measured)
Here is the decision this method is meant to support. The scenario is hypothetical. The names are placeholders, and no result in it was measured.
A platform team wants an agent that fixes broken CI environments: missing packages, misconfigured services, failing build scripts. Terminal-Bench-style tasks are a reasonable proxy. The team is choosing between two models, Model A and Model B. Model A ranks higher on a public leaderboard. The team’s own harness, Harness Y, uses structured tool calls and truncates command output to the last 200 lines. The leaderboard entry used Harness X, which drives a raw terminal and keeps full screen captures.
Four things can happen once the team runs the full 2×2 matrix:
- The ranking holds in both harnesses. The leaderboard was a good guide.
- The ranking flips in Harness Y. For example, Model A depends on seeing full output and loses more from truncation than Model B does.
- The ranking holds, but Model A costs several times more per solved task in Harness Y because it takes many more actions. For CI repair at scale, cost per solved task decides the question.
- The difference falls inside the noise. With a few dozen tasks and one attempt each, the confidence intervals overlap, and the leaderboard gap was never meaningful for this team.
You cannot tell which of the four you are in without running the matrix. Outcomes 2–4 are not exotic edge cases. They are the normal ways in which a single-number ranking misleads. The rest of this guide is the procedure for finding out.
4. Experiment design
4.1 The matrix
The minimum useful design is a full factorial of models × harnesses on the same task set with the same environment images. Two models in two harnesses give four cells. Do not compare a cell you ran yourself with a leaderboard cell. You cannot verify that the environment, task version, budgets and verifier match.
4.2 Attempts and sample size
Agent runs are stochastic even at temperature 0. Tool timing, API-side nondeterminism and environment state all introduce variance. Plan for:
- At least 3 attempts per task per cell if the budget allows. This lets you report both mean success and pass@k, and it shows which tasks are flaky.
- The full task set, not a hand-picked subset. If you must subsample, draw a random sample with a recorded seed and use the same subset for every cell.
With n independent tasks, a 95% confidence interval for a pass rate near 50% is roughly ±1/√n. For 80 tasks, that is about ±11 percentage points. Many headline differences between models are smaller than this, so section 7 uses paired statistics.
4.3 Fix the budgets before you look at results
Decide on the turn limit, the timeouts and the token caps in advance, and write them into the config. Raising the budget for the model you prefer after seeing a disappointing result is the agent-benchmark version of p-hacking.
5. Reproducible procedure
Step 1. Pin everything
Create an experiment directory and record what you are about to run:
mkdir -p mh-experiment/{configs,runs,normalized,reports}
cd mh-experiment

# Record tool and environment versions
python --version            > reports/versions.txt
docker --version           >> reports/versions.txt
pip freeze                 >> reports/versions.txt
git -C /path/to/harness-x rev-parse HEAD >> reports/versions.txt
git -C /path/to/harness-y rev-parse HEAD >> reports/versions.txt
date -u +%Y-%m-%dT%H:%M:%SZ >> reports/versions.txt
Also record the exact model identifiers as you pass them to the API, including any dated snapshot suffix. An alias such as “latest” can point to different weights next month.
Step 2. Write the matrix as a config file
Keep the experiment definition in one file that can be committed. The structure below is not a format any tool reads directly. It is the source of truth that your run script expands into individual commands.
# configs/matrix.yaml
experiment: ci-repair-model-harness-2026-10
dataset:
  name: terminal-bench-core      # check the exact name/version you install
  version: "PIN-ME"
  task_subset_seed: null         # null = full set; otherwise an integer seed
attempts_per_task: 3
budgets:
  max_turns: 50
  per_command_timeout_s: 180
  per_task_timeout_s: 1800
  max_output_tokens_per_turn: 8192
sampling:
  temperature: 0.0               # or vendor default; record whichever you use
models:
  - id: "model-a-PINNED-SNAPSHOT"
  - id: "model-b-PINNED-SNAPSHOT"
harnesses:
  - name: harness-x
    commit: "PIN-ME"
    config: configs/harness-x.yaml
  - name: harness-y
    commit: "PIN-ME"
    config: configs/harness-y.yaml
If one harness cannot enforce a budget that the other enforces, such as a per-turn token cap, write that down as a known asymmetry. Do not quietly drop the setting.
Step 3. Run every cell
For Terminal-Bench, the reference CLI has historically been tb run, with flags for the agent, the model, the dataset and the concurrency. The newer evaluation tooling around the project may use a different entry point. Run --help on the version you installed and adapt the command. The loop below shows the shape of the procedure and is not a verified invocation:
#!/usr/bin/env bash
# run_matrix.sh — example shape; verify flags with `tb run --help`
set -euo pipefail

DATASET="terminal-bench-core"
DATASET_VERSION="PIN-ME"
ATTEMPTS=3
MODELS=("model-a-PINNED-SNAPSHOT" "model-b-PINNED-SNAPSHOT")
AGENTS=("harness-x" "harness-y")

for model in "${MODELS[@]}"; do
  for agent in "${AGENTS[@]}"; do
    out="runs/${agent}__${model}"
    mkdir -p "$out"
    tb run \
      --dataset-name "$DATASET" \
      --dataset-version "$DATASET_VERSION" \
      --agent "$agent" \
      --model "$model" \
      --n-attempts "$ATTEMPTS" \
      --n-concurrent 4 \
      --output-path "$out" \
      2>&1 | tee "$out/console.log"
  done
done
Practical notes:
- Keep concurrency identical across cells. Shared CPU contention changes command timings and can trigger timeouts.
- Interleave cells over time if you suspect provider-side load effects. Running all of Model A on Monday and all of Model B on Tuesday confounds model with date.
- Keep API keys in environment variables or a secrets manager. Never put them in the config or the logs you publish. Check the logs for leaked headers before sharing them.
Step 4. Normalise the logs into one schema
Different harnesses log different things in different places. Before you aggregate, convert every trial into one JSON line with a fixed schema. This is the most important step: the comparison table can only be as fair as this schema.
{"task_id": "fix-broken-pip", "model": "model-a-PINNED-SNAPSHOT", "harness": "harness-x",
 "attempt": 1, "passed": true, "infra_error": false,
 "input_tokens": 0, "cached_input_tokens": 0, "output_tokens": 0,
 "actions": 0, "wall_seconds": 0.0, "stop_reason": "agent_done"}
Field definitions. Agree on these before you write the adapter:
| Field | Definition |
|---|---|
passed | The benchmark’s own verifier result. Never the agent’s self-report. |
infra_error | true when the trial failed for reasons outside the agent’s control, such as a container that failed to build, an API outage or a crash in the verifier. Keep these rows and flag them; never delete them. |
input_tokens | Total prompt tokens summed over all model calls in the trial, including cached tokens. |
cached_input_tokens | The subset of input tokens billed at a cache rate, if the provider reports it. Otherwise 0. |
output_tokens | All generated tokens, including reasoning or thinking tokens if the provider bills them. |
actions | The number of tool calls or commands executed in the environment. Count a batch of keystrokes sent in one turn as one action, and apply that rule to both harnesses. |
stop_reason | One of agent_done, max_turns, timeout, error. |
An adapter skeleton follows. Open one trial directory from each harness, find where it records the verifier result and token usage, and edit only extract(). Field names vary between harnesses and versions, so the paths below are placeholders.
#!/usr/bin/env python3
# normalize.py — convert one harness's trial outputs into the common JSONL schema
import json
import sys
from pathlib import Path

def extract(trial_dir: Path, model: str, harness: str) -> dict:
    # EDIT THIS FUNCTION for each harness. Paths and keys are placeholders.
    result = json.loads((trial_dir / "RESULT_FILE.json").read_text())
    usage = result.get("usage", {})
    return {
        "task_id": result["task_id"],
        "model": model,
        "harness": harness,
        "attempt": int(result.get("attempt", 1)),
        "passed": bool(result["is_resolved"]),
        "infra_error": result.get("failure_mode") in {"setup_error", "verifier_error"},
        "input_tokens": int(usage.get("input_tokens", 0)),
        "cached_input_tokens": int(usage.get("cached_input_tokens", 0)),
        "output_tokens": int(usage.get("output_tokens", 0)),
        "actions": int(result.get("n_commands", 0)),
        "wall_seconds": float(result.get("duration_s", 0.0)),
        "stop_reason": result.get("stop_reason", "unknown"),
    }

def main(run_dir: str, model: str, harness: str, out_path: str) -> None:
    with open(out_path, "a", encoding="utf-8") as out:
        for trial in sorted(Path(run_dir).glob("**/RESULT_FILE.json")):
            row = extract(trial.parent, model, harness)
            out.write(json.dumps(row) + "\n")

if __name__ == "__main__":
    main(*sys.argv[1:5])
python normalize.py runs/harness-x__model-a-PINNED-SNAPSHOT model-a-PINNED-SNAPSHOT harness-x normalized/runs.jsonl
# ...repeat for each cell...
wc -l normalized/runs.jsonl # expect: tasks × attempts × cellsIf the line count differs from tasks × attempts × cells, stop and find the missing trials before you continue. Silently missing trials are the most common source of inflated scores.
Step 5. Add prices from the official price list
Write current prices into a file. Take them from the provider’s official pricing page on the day you run, and record that date. This article gives no prices on purpose: they change, and a stale number in a cost column is worse than an empty one.
{
  "_source_note": "Copied from provider pricing pages on YYYY-MM-DD; USD per 1M tokens",
  "model-a-PINNED-SNAPSHOT": {"input_per_mtok": null, "cached_input_per_mtok": null, "output_per_mtok": null},
  "model-b-PINNED-SNAPSHOT": {"input_per_mtok": null, "cached_input_per_mtok": null, "output_per_mtok": null}
}
Save this as configs/prices.json. The aggregation script prints n/a for cost while any price is null, so an empty field can never pass for a real figure.
Step 6. Aggregate into the model + harness table
#!/usr/bin/env python3
# aggregate.py — build the model x harness comparison table from normalized JSONL
import json
import math
import statistics
import sys
from collections import defaultdict

def wilson(k: int, n: int, z: float = 1.96):
    if n == 0:
        return float("nan"), float("nan")
    p = k / n
    denom = 1 + z * z / n
    centre = (p + z * z / (2 * n)) / denom
    half = z * math.sqrt(p * (1 - p) / n + z * z / (4 * n * n)) / denom
    return centre - half, centre + half

def trial_cost(row: dict, prices: dict):
    p = prices.get(row["model"])
    if not p or any(p.get(k) is None for k in ("input_per_mtok", "output_per_mtok")):
        return None
    cached = row.get("cached_input_tokens", 0)
    fresh = row["input_tokens"] - cached
    cached_rate = p.get("cached_input_per_mtok")
    if cached_rate is None:
        cached_rate = p["input_per_mtok"]
    return (fresh * p["input_per_mtok"]
            + cached * cached_rate
            + row["output_tokens"] * p["output_per_mtok"]) / 1_000_000

def pass_at_k(rows: list, k: int):
    by_task = defaultdict(list)
    for r in rows:
        by_task[r["task_id"]].append(r)
    solved = 0
    for attempts in by_task.values():
        attempts.sort(key=lambda r: r["attempt"])
        if any(r["passed"] for r in attempts[:k]):
            solved += 1
    return solved / len(by_task) if by_task else float("nan")

def main(runs_path: str, prices_path: str, k: int = 3) -> None:
    with open(prices_path, encoding="utf-8") as f:
        prices = json.load(f)
    groups = defaultdict(list)
    with open(runs_path, encoding="utf-8") as f:
        for line in f:
            if line.strip():
                r = json.loads(line)
                groups[(r["model"], r["harness"])].append(r)

    header = ["model", "harness", "trials", "infra err", "pass rate", "95% CI",
              f"pass@{k}", "mean tokens", "median actions", "cost/trial", "cost/solved"]
    print("| " + " | ".join(header) + " |")
    print("|" + "---|" * len(header))

    for (model, harness), rows in sorted(groups.items()):
        n = len(rows)                                   # strict denominator: infra errors count as failures
        k_pass = sum(1 for r in rows if r["passed"])
        infra = sum(1 for r in rows if r.get("infra_error"))
        lo, hi = wilson(k_pass, n)
        tokens = [r["input_tokens"] + r["output_tokens"] for r in rows]
        actions = [r["actions"] for r in rows]
        costs = [trial_cost(r, prices) for r in rows]
        if all(c is not None for c in costs):
            total = sum(costs)
            cpt = f"{total / n:.4f}"
            cps = f"{total / k_pass:.4f}" if k_pass else "—"
        else:
            cpt = cps = "n/a"
        print("| " + " | ".join([
            model, harness, str(n), str(infra),
            f"{k_pass / n:.1%}", f"{lo:.1%}–{hi:.1%}",
            f"{pass_at_k(rows, k):.1%}",
            f"{statistics.mean(tokens):,.0f}",
            f"{statistics.median(actions):g}",
            cpt, cps,
        ]) + " |")

if __name__ == "__main__":
    main(sys.argv[1], sys.argv[2], int(sys.argv[3]) if len(sys.argv) > 3 else 3)
python aggregate.py normalized/runs.jsonl configs/prices.json 3 | tee reports/table.mdThree design choices in this script are deliberate:
- The pass-rate denominator includes infra errors. This is the conservative choice. If infra errors are frequent, report a second pass rate that excludes them, label it clearly, and fix the infrastructure before you draw conclusions.
- Cost per solved task is total cost divided by solved count. Failed trials still cost money, so they are included. For deployment decisions, this column often matters more than the pass rate.
- Actions use the median, tokens use the mean. Action counts are skewed by runaway loops, and the median resists that skew. The mean token count multiplies directly into cost.
Step 7. The table you should end up with
Template. Every cell stays empty until you have measured it:
| Model | Harness | Pass rate (95% CI) | pass@3 | Mean tokens / trial | Median actions | Cost / solved task | Infra errors |
|---|---|---|---|---|---|---|---|
| Model A | Harness X | — | — | — | — | — | — |
| Model A | Harness Y | — | — | — | — | — | — |
| Model B | Harness X | — | — | — | — | — | — |
| Model B | Harness Y | — | — | — | — | — | — |
Read it in this order:
- Within a harness, across models. This is the closest you get to a model comparison. It is still conditional on that harness.
- Within a model, across harnesses. This is the harness effect. If it is as large as the model effect, then the harness choice is as important as the model choice.
- Interaction. Does the model ranking change between harnesses? If it does, no harness-free answer to “which model is better” exists for this task family.
- Efficiency. Among cells whose confidence intervals overlap, prefer the lower cost per solved task and the lower median actions. Fewer actions also mean fewer chances to do damage in a real environment.
6. A paired comparison: same tasks, different pairs
Independent confidence intervals waste information, because every cell ran the same tasks. A paired test asks a sharper question: on the tasks where the two configurations disagree, which one wins more often? The script below uses attempt 1 of every task and runs an exact sign test on the discordant tasks, which is the exact form of McNemar’s test.
#!/usr/bin/env python3
# compare.py — paired comparison of two model+harness configurations
import json
import sys
from math import comb

def load(path, model, harness, attempt=1):
    out = {}
    with open(path, encoding="utf-8") as f:
        for line in f:
            if not line.strip():
                continue
            r = json.loads(line)
            if r["model"] == model and r["harness"] == harness and r["attempt"] == attempt:
                out[r["task_id"]] = bool(r["passed"])
    return out

def exact_two_sided(b: int, c: int) -> float:
    n = b + c
    if n == 0:
        return 1.0
    tail = sum(comb(n, i) for i in range(0, min(b, c) + 1)) / 2 ** n
    return min(1.0, 2 * tail)

def main(path, m1, h1, m2, h2):
    a = load(path, m1, h1)
    b = load(path, m2, h2)
    common = sorted(set(a) & set(b))
    only_a = sum(1 for t in common if a[t] and not b[t])
    only_b = sum(1 for t in common if b[t] and not a[t])
    both = sum(1 for t in common if a[t] and b[t])
    neither = len(common) - only_a - only_b - both
    print(f"tasks compared: {len(common)}  (missing in one side: {len(set(a) ^ set(b))})")
    print(f"both solved: {both}  neither: {neither}")
    print(f"only {m1}/{h1}: {only_a}")
    print(f"only {m2}/{h2}: {only_b}")
    print(f"exact sign test p = {exact_two_sided(only_a, only_b):.4f}")

if __name__ == "__main__":
    main(*sys.argv[1:6])
python compare.py normalized/runs.jsonl \
model-a-PINNED-SNAPSHOT harness-y \
model-b-PINNED-SNAPSHOT harness-yRun this comparison for the pairs you care about: two models in your production harness, and one model across two harnesses. If you run many comparisons, the p-values need a multiple-comparison correction; a simple Bonferroni correction is acceptable for a handful. Also read the lists of discordant tasks by hand. They often reveal a harness-specific failure that a statistic cannot show, for example every “only B” task involves an interactive program.
7. Verification checklist
Before you publish or act on the table, confirm each item:
- ☐ The row count in
runs.jsonlequals tasks × attempts × cells. - ☐ Every cell used the same dataset version, the same task list and the same container images.
- ☐ The budgets in each harness config match
matrix.yaml, or the asymmetries are documented. - ☐
passedcomes from the benchmark verifier in every row, never from the agent’s claim. - ☐ Infra errors are counted and shown. If they are concentrated in one cell, that cell is re-run or flagged.
- ☐ The token counts for a few trials were checked by hand against the provider’s usage dashboard or billing export.
- ☐ The action counts for a few trials were checked by hand by reading the trajectory.
- ☐
prices.jsoncarries a source note and a date, and no field isnullif a cost column is shown. - ☐
versions.txt, the configs and the scripts are committed next to the report. - ☐ At least five trajectories per cell, both passes and failures, were read end to end.
The last item is not optional. Aggregate numbers will not tell you that a harness marks tasks complete after the model printed “done” without doing anything, or that a timeout killed a run that was one command from success.
8. Failure cases to look for
8.1 Silent truncation
The harness cuts terminal output, and the model never sees the actual error. Symptom: repeated near-identical commands in the trajectory and a high median action count in one harness only. Check: diff the raw command output against what the model received.
8.2 Premature completion
The model declares success without verifying anything. Some harnesses require confirmation before accepting “done”; others accept it immediately. Symptom: low action counts with low pass rates. Check: the share of stop_reason = agent_done among failed trials.
8.3 Budget exhaustion masquerading as model weakness
A model that explores more hits the turn limit more often. Symptom: many failures with stop_reason = max_turns. This is a legitimate result for that budget. Report it as one, and do not generalise it to “the model cannot do the task”.
8.4 Tool-format mismatch
A model trained on one tool-calling convention emits malformed calls in a harness that expects another. Symptom: parse errors or retries in the harness logs. Whether these errors count against the model is a policy decision. Make it explicitly.
8.5 Infrastructure noise attributed to the model
Rate limits, container start failures and verifier crashes. Symptom: failures clustered in time or concentrated on particular tasks across all cells. Check: plot failures by start timestamp.
8.6 Contamination and overfitting of the harness
Harness prompts tuned on the benchmark’s own tasks can produce scores that do not transfer. If you developed the harness while looking at these tasks, hold out a split you have never inspected and report it separately.
8.7 Unequal reasoning or thinking budgets
One harness sets a high reasoning effort and the other uses the vendor default. Both cost and pass rate move together, and you end up comparing budgets rather than harnesses. Record the setting per cell.
9. Limitations of this method
- The result is conditional on the task family. A table built on terminal tasks says little about browsing, data analysis or long-horizon coding.
- Small task sets give wide intervals. With tens of tasks, only large differences are detectable. Report the intervals, and do not round them away.
- Cost is a snapshot. Prices, caching behaviour and model snapshots change. A cost column is valid for the date in
prices.json. - Token accounting differs between providers. Reasoning tokens, cached tokens and tool-definition overhead are reported inconsistently. Cross-provider token comparisons are approximate unless you verify them against billing.
- The action definition is a convention. Counting keystroke batches and counting structured calls are not perfectly comparable. Apply one rule to all cells and state it.
- Two harnesses are not “the harness space”. Your matrix samples a few points. It shows that the harness matters and by how much for these points. It does not identify the best possible harness for a model.
- Public leaderboard cells are not comparable with yours unless you can reproduce their environment, budgets and dataset version exactly.
10. How to report the result honestly
When you share the table, internally or publicly, include:
- The full matrix, including the cells that make your preferred option look worse.
- The pass rate with confidence intervals, the trial count and the infra-error count per cell.
- Cost per solved task with a dated price source, or an explicit “cost not computed”.
- Median actions and mean tokens per trial.
- Paired comparison results for the claims you make.
- Harness identities (commit and config), model snapshots and the dataset version.
- A sentence of the form: “These results describe model + harness pairs on this task set under these budgets.”
That last sentence answers the question in the title. Почему агентные бенчмарки измеряют модель вместе с оболочкой? Because the quantity being measured is the behaviour of a loop, and the model is only one part of that loop. Report the loop.
Next steps
Continue with the practical guides on testing and controlling agents in the guides section, and look up any unfamiliar term in the glossary.